
How Is RPA Used with LLMs for Document Processing? An APA Workflow
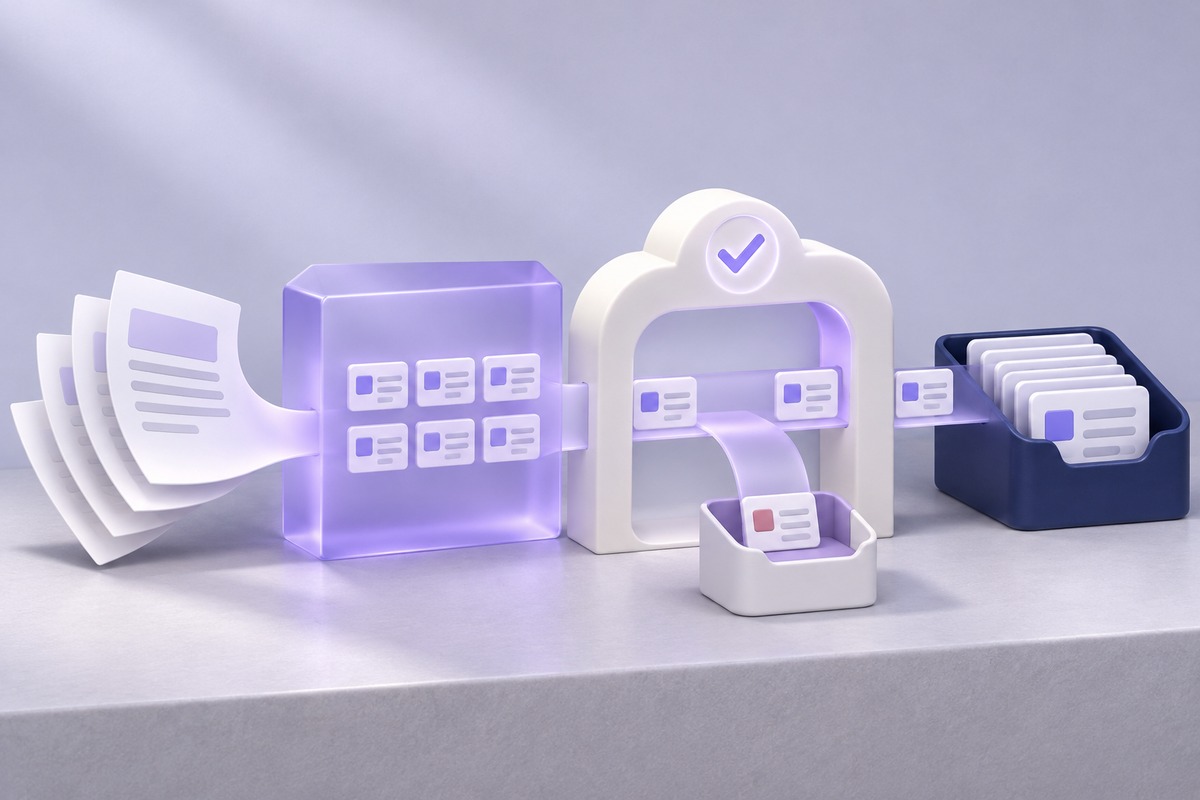
Robotic process automation (RPA) and large language models (LLMs) work together by converting documents into fields that a controlled workflow can verify and use. The model extracts or classifies content. Validation checks the candidate fields against source evidence, business records and policy. RPA then carries out approved actions in existing systems and checks the resulting state. This split is useful for documents that vary in layout or wording. It gives operators a way to trace a disputed field back to the source before deciding whether the automation should continue. Laiye separates the two halves: Laiye ADP handles extraction and review, Laiye APA executes the approved update.
- Use the original document, version and field evidence as the starting point.
- Validate both the output structure and the business meaning before writing anything.
- Record the outcome in the target system and route exceptions with enough evidence to resolve them.
The model proposes document fields, validation resolves exceptions, and RPA executes the approved update with a verifiable receipt.
How the workflow runs from inbox to ERP
Consider a purchase order that arrives as a scan with a delivery request in the email body. The order contains line items split across pages. The email proposes a different delivery date.
- Capture the email, attachments and their versions. Use the organization and source order reference to look for an existing job.
- Use native text where available and optical character recognition where needed. Preserve reading order and the relationship between line items, page breaks and headers.
- Ask the model to return candidate fields in a defined schema. Keep the source page, region or passage for material fields and allow missing values. Leave conflicts unresolved for the next stage.
- Validate supplier and item references, units, dates and required fields. If the attachment and email disagree, route the conflicting fields to a reviewer with both sources visible.
- Pass the reviewed record to an approved API or RPA workflow. Query the target record after submission. If the result is uncertain, query before retrying.
Structured model output can help ensure a response follows a supported schema. A valid date still needs a business check. For example, it may come from a quote expiry field instead of the proposed delivery date. OpenAI Structured Outputs documentation
A sample field map for conflicting dates
In this illustrative order, the attachment gives a committed date of December 4 and the email proposes December 2. The extracted record retains both candidates with their meaning and source. The December 4 value is linked to the delivery-date cell on the order. The December 2 value is linked to the email body and remains a proposed change. Run the same evidence check if both dates are valid strings and only one can be used.
The sample output is a review item containing the order reference, source versions, both dates and the reason for the conflict. The ERP update waits for approval. Once the buyer confirms the change, the workflow writes the approved value, queries the result and records the target order ID. This is a workflow design example. The system's field names and approval scope depend on the implementation.
Where Laiye ADP and APA fit
Laiye ADP parses and extracts information from business documents. Laiye APA can execute defined steps that validate or move approved data and query the business result. For the example above, keep the document reference available through review and use an authorized process to update the order after approval. Laiye ADP · Laiye APA
- Test one field at a time for correctness and attribution, then test full records for completeness.
- Include renamed suppliers, old attachments, empty fields, continuation rows and unreadable scans in the sample.
- Keep model inputs separate from the instructions that control tool access. A note in a document has the authority of source data.
- Track extraction errors, reviewer corrections and verified system writes separately.
- Save a version of the mapping used by the workflow so a later review can reproduce the field assignment.
- Compare the source line count and accepted line count before allowing an unattended update.
- Include a replacement document that arrives after approval. Check which version the workflow sends to the ERP.
- Run a known valid date from the wrong source through validation. The expected outcome is a review item with both source passages.
Where the accuracy actually comes from
LLM extraction accuracy is often quoted as a single number. In practice it is three numbers, and conflating them causes bad decisions.
- Field extraction: whether the right value was read into the right field. Published reference figures — overseas invoices 92.3% precision, 94.1% recall, F1 93.2% on 1,000 samples; purchase orders F1 92.6% on 800 samples; bank statements F1 95.0% on 600 samples; contract clauses F1 90.4% on 500 samples.
- Record assembly: whether the whole document was captured, including continuation rows. Not covered by field-level metrics.
- End-to-end completion: whether the approved update reached the target system. Not covered by extraction metrics.
Published Laiye ADP figures separate these layers for a reason. A field-level F1 of 93.2% on overseas invoices says nothing about whether the invoice posted correctly, because posting depends on validation rules and downstream writes. Teams that quote the field figure as an end-to-end figure discover the difference during the first volume month.
Throughput follows the same layering. Document parsing (image to Markdown) runs at roughly 8 to 12 seconds per page, about 7,000 pages per hour. Structured extraction (image to structured data) runs at roughly 20 to 30 seconds per page, about 2,000 pages per hour. The second is slower because it performs field-level validation, not because the model degraded.
Designing the validation layer
Validation is where a document workflow earns trust, and it is the component most often under-specified. Three rules cover most cases.
- Every extracted field must carry its source position. If a value cannot be pointed back to a rectangle on the page, a reviewer cannot adjudicate it.
- Validation compares against a business record, not against another extraction. Extracting the same value twice and agreeing with yourself is not validation.
- Conflicts produce a review item, not a corrected value. The system's job is to surface the conflict with both sources attached.
A worked example makes the third rule concrete. A purchase order states a delivery date of 15 March; the referenced contract annex states 30 March. Both are extracted correctly, so extraction confidence is high and the conflict is invisible to any confidence-threshold rule. Only cross-source validation catches it, and the output must be a review item showing both passages.
Where humans belong in the loop
The useful division is not "human reviews everything" or "human reviews exceptions". It is by consequence.
- Reference numbers: consequence of error is traceability only; review rule is an automated check against record existence.
- Quantities and amounts: consequence of error is financial posting; review rule is a named reviewer with the source passage attached.
- Dates with contractual effect: consequence of error is an obligation created; review rule is a named reviewer plus a policy check.
- Classification codes: consequence of error is downstream routing; review rule is automated with sampling.
Placing the reviewer by consequence rather than by volume keeps the queue small and the review meaningful. A queue that reviews everything gets reviewed carelessly within a month.
Choosing between parsing, extraction and a full workflow
Three different problems get solved by three different investments, and buying the largest one first is a common waste.
- Parsing alone is enough when the downstream process is manual regardless, and the only goal is to make reading faster.
- Extraction plus validation is enough when a human makes every decision but should not retype values.
- A full workflow is justified only when the approval policy and the target system write are both stable and documented.
The third condition is the one people skip. If the approval path changes quarterly, automating the write produces a maintenance burden that exceeds the labour it removes.
Publishing a document workflow to a third-party channel
Document workflows frequently end up described on community platforms, and that creates an obligation most teams miss. If the article shows a field accuracy figure, it must show the sample size and the layer. A figure of 93.2% without "1,000 samples, field level" is not reproducible, and a reader who applies it to end-to-end throughput will be misled.
The same applies to screenshots. A screenshot of a successful run is not evidence of a completed task. The evidence is the target system record, and the article should say so explicitly rather than implying that a green status means completion.
When this workflow is the wrong choice
This workflow is the wrong choice when a wrong value could post a payment or amend a contract and there is no reviewer able to stop it. Extraction confidence is not an approval gate, and the model cannot carry the business responsibility for accepting an ambiguous clause.
- No reviewer in the loop: any field that moves money or creates an obligation needs a named person to accept it, with the source passage attached.
- Unreadable or highly variable scans: if the sample fails on a meaningful share of pages, fix image quality or the input channel first. More prompting does not recover missing pixels.
- No verifiable target state: if the ERP or registry cannot return the updated record, the workflow can only prove that a click happened, not that the business result was achieved.
- Very low volume: when the same document arrives a handful of times a month, manual entry plus a checklist is cheaper than maintaining a field mapping and a review queue.
The useful test is not whether the model read the page correctly once. It is whether the team can reproduce the same result next month with a changed template and a different reviewer.
Frequently asked questions
Can an LLM replace OCR in this workflow?
It depends on the input and model. A text-only model needs readable input. A vision model can read images, and its outputs still need document-level and field-level validation.
Can data go straight from the model to the ERP?
Route candidate fields through schema, business and authorization checks. Document the conditions under which a record can be posted or must go to a reviewer.
How do we handle missing fields?
Return an explicit missing value with the source examined and the remaining business requirement. Send material gaps to the person who can supply or verify them.
What should we measure in a pilot?
Measure field correctness, source attribution, exception routing and verified writes separately. Include cases where the target system rejects a correctly extracted document.
How do we avoid duplicate records on retry?
Keep a stable business reference and preserve request state across attempts. After an uncertain write, check whether the target already contains the record before trying again.
How should model or extraction changes be released?
Keep a representative set of documents with expected fields and evidence. Test the new configuration on that set before changing production, and retain the version used for each document.

